A working media practice runs on more machines than anyone admits. The NAS holding a decade of RAW files. The render box chewing through 4K exports overnight. The little VPS serving your portfolio. The ingest server your camera uploads to from the field. Every one of them is quietly writing down everything that happens — and almost none of it is askable. "Did last night's exports finish?" means SSH and squinting at a queue folder. "How many people actually looked at the wedding gallery?" means grepping an access log. "Did Tuesday's shoot get backed up?" usually means: you hope so.
Today we're shipping the fix. Server Agents turn the 5am CLI into a lightweight agent you deploy on your own machines — and turn your AI characters into something that can answer questions about them, in plain English, in the same chat where you already talk about your albums:
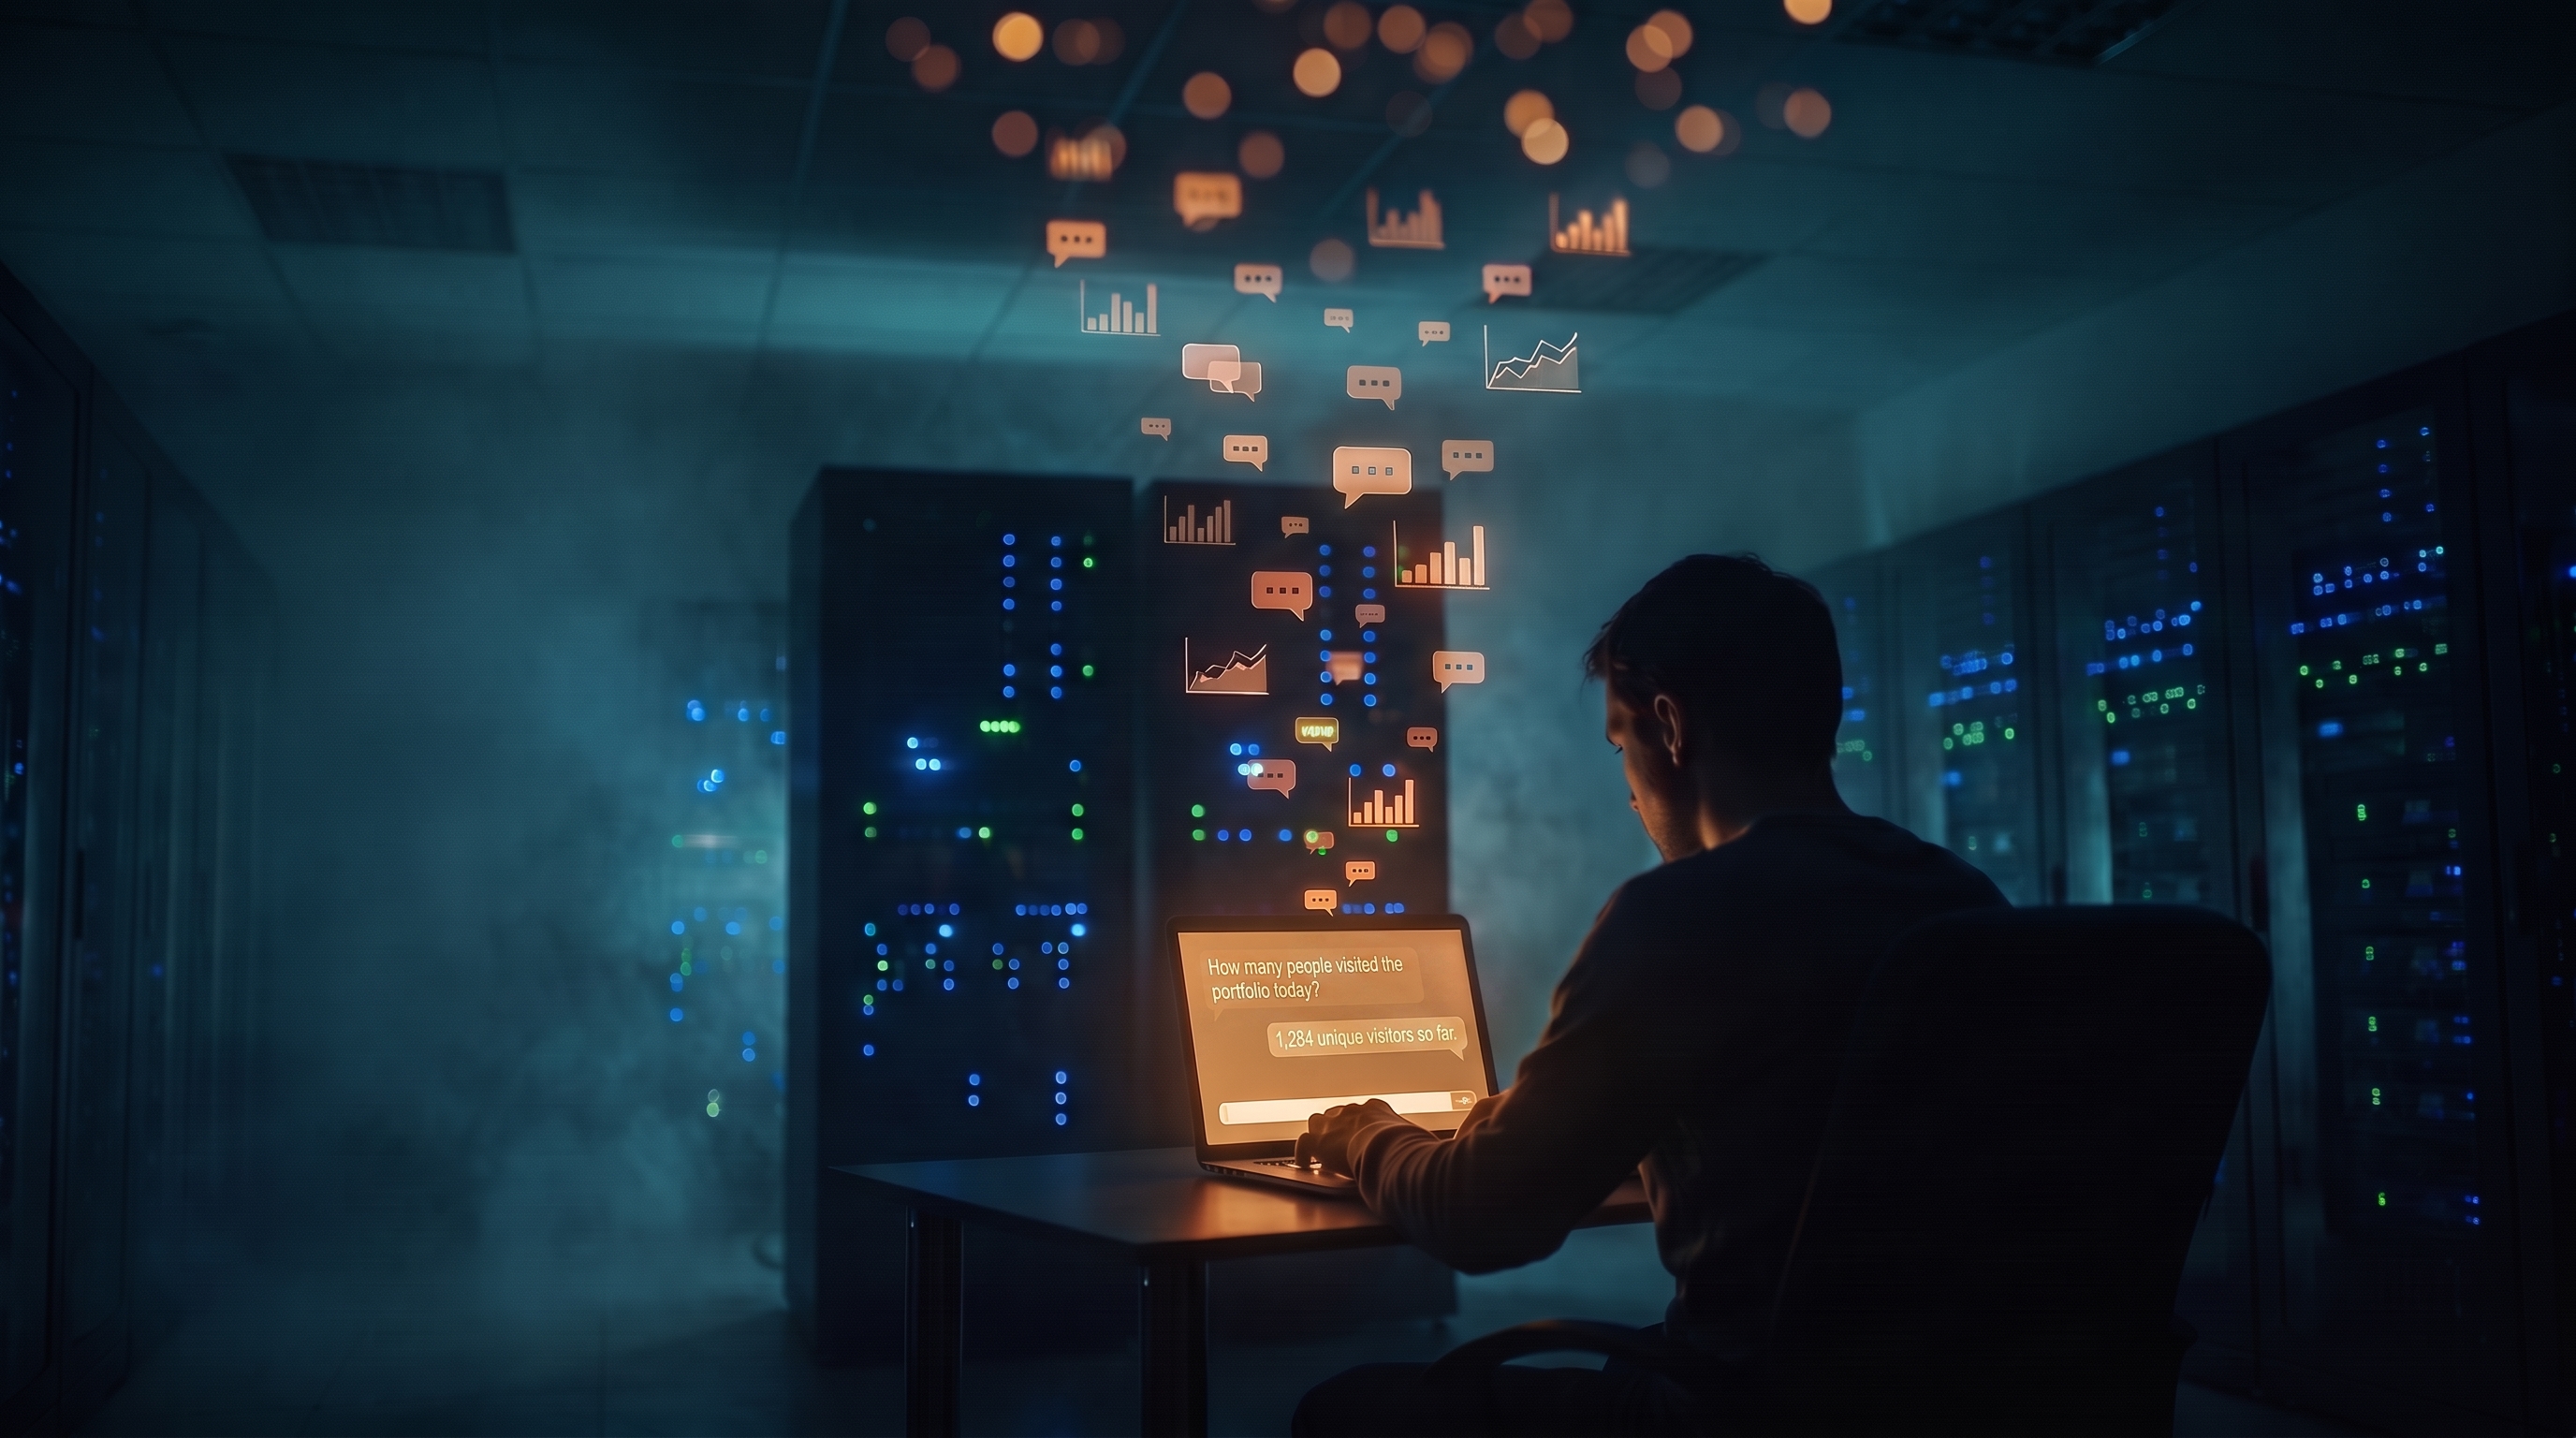
You: how many distinct IP addresses requested the portfolio in the last 24 hours?
Your character: 1,284 distinct IP addresses in the loaded access logs for the last 24 hours. This is not a count of individual people.
This dialogue and the numeric outputs below are illustrative, not a measured customer session. The query runs on your server; response time depends on connectivity, dataset size, and model latency.
What stays local, and what leaves
The agent stores ingested log lines and file inventories in SQLite on your machine. It answers structured queries locally and returns bounded results, such as a count or a list of paths. It does not bulk-upload that database for cloud indexing.
Those results leave the machine. They pass through 5AM into the character conversation and can be sent to the AI provider. A path, IP address, or filename in a result may itself be sensitive. Skill outputs can disclose additional information. Select datasets, fields, skills, and operating-system permissions with that in mind.
The agent query audit record tracks operational metadata rather than storing the full result body. That limited audit record does not imply that conversation content or provider requests contain no results. See the server-agent reference for the query and security model.
An outbound agent connection
The second thing we refused to do: ask you to open a port. Exposing an HTTP service on your NAS or render box means TLS certificates, firewall rules, and a new attack surface per machine — a real tax, and the reason most self-hosted integrations die on the vine.
Instead, the server-agent connection dials out. It holds a long-poll HTTPS connection to 5AM (the same trick GitHub Actions runners use); when your character asks something, the query is waiting on the agent's already-open poll, gets executed locally, and the result flows back — resolving directly into the character's chat turn while it's still thinking. A Synology in a closet, a render box behind studio NAT, a Raspberry Pi tethered to hotel Wi-Fi: if it can reach 5am.app over HTTPS, it works.
Offline and no-data responses instruct the character to report the problem rather than estimate a value. Check the tool result and agent status when an answer matters: instructions cannot guarantee that a model will describe an outage correctly.
Walkthrough: a talking portfolio, start to finish
Start with a server that keeps an nginx or Apache access log. A line records an HTTP request, not a visit: one page can generate many requests, and bots may appear too. Log retention and rotation determine how much history you can load.
We'll go slowly. If you can SSH into a server and paste commands, you can do all of this.
Before you start
For this walkthrough you need:
- A server you can SSH into, running your site. Any Linux VPS is fine — a $6 DigitalOcean droplet, a Hetzner box, an old machine in a closet.
- The 5am CLI installed on it. One line:
curl -fsSL https://cli.5am.app/cli/latest/install.sh | sh - A 5AM account with AI Characters access (Premium or Ultra), available AI credits or your own supported Gemini key, and permission to read the logs. The agent and local data commands are separate from billed character conversations.
- A Linux host using systemd for the service instructions. The archive example additionally needs Python 3. Replace paths and usernames with your own; keep a copy of the source logs.
A few words you'll meet along the way, in plain terms:
| Term | What it means here |
|---|---|
| Dataset | A table of rows on your server. One row per log line, per metrics sample, per file. |
| Schema | A short list saying what fields a row has and what type each one is. You write it once. |
| Agent | The 5am CLI running continuously on your machine, waiting for questions. |
| Daemon | A program that runs in the background forever, rather than finishing and exiting. |
| systemd | The thing on Linux that starts programs at boot and restarts them if they crash. |
Step 1 — log in with a read-only library token
5am login
This links the CLI to your account. When it asks for a token, mint a read-only one in Settings → Keys, under CLI Access Tokens. Leave the scope as read, which is already selected for you.
Every agent endpoint is designed to need nothing more than read, so that's genuinely enough — and it means that if someone ever gets hold of the token sitting on this server, it cannot upload, change, or delete anything in your library. This limits library access; it does not limit what local custom commands can do with the operating-system permissions of the agent process.
Step 2 — describe your data once
A schema is just a list of field names and types. This one matches what the built-in nginx/Apache log parser produces:
cat > requests.schema.json <<'EOF'
{
  "fields": {
    "ip": "string", "method": "string", "path": "string",
    "status": "number", "bytes": "number", "ts": "timestamp"
  },
  "time_field": "ts"
}
EOF
time_field tells the agent which field to use when you ask about "the last 24 hours".
Take all six fields even if you only think you need two. A dataset remembers the schema it was created with, and re-ingesting later with a different set of fields is refused rather than silently merged. That's the safe behaviour — it means nothing ever half-migrates — but it does mean the two-field schema you dash off today blocks the six-field one you want next month until you rebuild with --replace. method and bytes are free right now.
Step 3 — load the log
5am data ingest --dataset requests --schema requests.schema.json \
    --file /var/log/nginx/access.log --format combined
--format combined is the standard nginx/Apache log layout, parsed for you — no converter to write. You'll see something like:
{ "dataset": "requests", "rows_ok": 15231, "rows_rejected": 0 }
If rows_rejected is high, your log isn't in that format — nginx can be configured to write JSON instead, which the agent also reads.
Permission note: on Debian/Ubuntu the nginx logs are readable only by
rootand theadmgroup. If you get a permission error and you're running as a non-root user,sudo usermod -aG adm youruserfixes it (log out and back in afterwards).
This command is safe to run again. It records how far it got — a byte offset saved in the same database transaction as the rows — so a second run picks up only the lines that arrived since. Run it from cron every minute, or add --follow to have it tail the file continuously. Checkpointing handles supported rotation and partial-line cases, but retained source logs and spot checks are still needed to detect missing or repeated requests after an outage.
Step 4 — check it yourself before involving the AI
5am data query --dataset requests --op count_distinct --field ip --since -24h
{ "op": "count_distinct", "dataset": "requests", "field": "ip", "value": 1284 }
This is the query engine the character uses. Compare its result with the original log, then check that chat requests the same operation, field, and time window. Distinct IPs are not unique visitors: shared networks combine people, changing addresses split people, and bots inflate counts. This dataset cannot establish time spent on a gallery from an IP count.
Step 5 — run the agent (and keep it running)
5am serve agent --name portfolio
It'll print that it registered, then sit there. That's the catch. This is a daemon — it holds its connection open forever waiting for questions, so it never returns you to the prompt. Close the SSH session and it dies with it. 5am agent list will then show your agent registered but "online": false, and your character will (correctly) say the machine isn't answering.
So press Ctrl-C, and let the operating system run it properly instead. On Linux that means a systemd unit — a small text file telling the system "start this at boot, restart it if it dies":
# /etc/systemd/system/5am-agent.service
[Unit]
Description=5AM server agent
After=network-online.target

[Service]
User=youruser
Environment=HOME=/home/youruser
ExecStart=/usr/local/bin/5am serve agent --name portfolio
Restart=always
RestartSec=5

[Install]
WantedBy=multi-user.target
sudo systemctl daemon-reload
sudo systemctl enable --now 5am-agent    # start it, and at every boot
systemctl status 5am-agent               # should say: active (running)
Two details that trip people up: ExecStart needs the full path to the binary (which 5am will tell you), because systemd doesn't search your PATH; and it doesn't run a shell, so shell tricks like & don't work there — nor are they needed, since systemd is doing the backgrounding.
Writing that file once is fine. If you're setting up several machines, there's a copy-and-adapt installer that generates it for you — install-agent.sh, covered near the end of this post.
Step 6 — turn it on for a character
In the web UI, open a character and enable the Query Server Agent skill. There's nothing else to configure — the character discovers your machines, their datasets, and the fields in each, automatically.
Then just ask:
You: how many distinct IP addresses appear in the portfolio log in the last 24 hours?
Your character: 1,284 distinct IP addresses in the loaded access logs for the last 24 hours. This is not a count of individual people.
"Which gallery page gets the most traffic?", "any spike after I posted the new series?" — chat messages now, not shell sessions.
If something doesn't work
| What you see | What it usually means |
|---|---|
"online": false in 5am agent list | The agent isn't running. It was started in a shell that has since closed — see Step 5. |
| Character says the machine is offline | Same thing, or the agent restarted less than a minute ago; it re-registers within about 90 seconds. |
already exists with a different schema | You created that dataset earlier with different fields. Either match the old schema, or add --replace to rebuild it from scratch (this drops the old rows). |
rows_rejected is large | The log isn't in the format you told it. Check --format, or switch nginx to JSON logging. |
| Permission denied reading the log | Add your user to the adm group (see the note in Step 3). |
command not found: 5am under sudo | sudo uses a restricted PATH. Use the full path from which 5am. |
Query a file inventory without confusing timestamps with arrivals
This example builds a snapshot of file sizes, paths, and modification times. It does not record when a file arrived on the NAS or prove a backup completed. For those questions, ingest your transfer or backup tool's verified completion log.
Create the schema and an output directory you own:
mkdir -p ./archive-agent
cat > ./archive-agent/archive.schema.json <<'EOF'
{"fields":{"bytes":"number","ts":"timestamp","path":"string"},"time_field":"ts"}
EOF
python3 - <<'PYTHON'
import json
from datetime import datetime, timezone
from pathlib import Path
archive = Path('/mnt/archive')  # change this to your archive
if not archive.is_dir():
    raise SystemExit(f'Archive directory not found: {archive}')
with Path('./archive-agent/archive.jsonl').open('w') as output:
    for file in archive.rglob('*'):
        if file.is_file():
            info = file.stat()
            row = {'bytes': info.st_size,
                   'ts': datetime.fromtimestamp(info.st_mtime, timezone.utc).isoformat(),
                   'path': str(file)}
            output.write(json.dumps(row) + '\n')
PYTHON
5am data ingest --dataset archive --schema ./archive-agent/archive.schema.json \
  --replace --file ./archive-agent/archive.jsonl
--replace discards the previous dataset snapshot. Use a separate dataset name if you need to preserve it. Review inventory generation errors before ingesting: inaccessible files, changing files, or missing mounts can make a snapshot incomplete.
Ask: “How many files in the loaded snapshot have modification times this month?” Do not describe the result as “new files this month.” A copied file can retain an old modification timestamp.
The bundled metrics sampler provides a separate dataset for CPU, memory, and disk. Check sample freshness before interpreting a latest value as current machine health.
The server your site actually runs on
The examples so far are storage and pixels. The other machine worth wiring up is the one running your application — and it's the case where a dataset and a live check are genuinely different questions.
We ship a ready-made sampler for exactly this. It prints one line of JSON describing the three layers that decide whether a web app is healthy:
- The machine — CPU, memory, disk, load
- The processes — how many are running, how many have crashed, how many times they've been restarted
- The database — reachable at all, how fast it answers, how many connections are open, how big it's grown
One line looks like this (values illustrative):
{"cpu_pct":18.4,"load1":0.7,"mem_pct":61.2,"disk_pct":47,
 "pm2_up":1,"pm2_online":4,"pm2_errored":0,"pm2_restarts":12,
 "db_up":1,"db_latency_ms":3,"db_connections":11,"db_size_mb":2140,
 "ts":"2026-01-15T09:30:00.000Z"}
You don't have to read that — the character does. Sample it every minute into a dataset and the history becomes conversational: "was the database slow last night?", "when did the app last restart?", "how fast is the disk filling up?"
The important design choice is what happens when something is broken. A database the sampler can't reach is recorded as db_up: 0 — a fact, stored like any other — rather than an error that aborts the sample. So an outage leaves a visible run of zeros in your history instead of a gap where the data should be. "The database was down from 02:10 to 02:40" is a question you can only answer if something wrote that down at the time.
The same script also makes a good custom skill, and that pairing is the point. The dataset answers "was it healthy overnight?" from stored history; the skill runs the sampler on demand and answers "is it healthy right now?" — the question you actually ask when something feels wrong. Same code, two very different questions, and the character picks between them.
Teach it your studio's tricks: custom skills in the chat UI
Datasets cover anything you can record. But some questions need to be answered by running something — checking the render queue, sizing a shoot folder, verifying a backup. For those, you define custom skills: small JSON manifests in ~/.5am/skills/ on the machine, each declaring a name, a description, an argument schema, and the exact command to run.
Two configuration examples. First, an argv-style skill — the model fills {{shoot}}, and arguments are passed without any shell parsing:
{
  "name": "shoot_disk_usage",
  "description": "Total size on the studio NAS of a shoot folder, e.g. 2026-07-12-hernandez-wedding",
  "input_schema": {
    "type": "object",
    "properties": {
      "shoot": { "type": "string", "description": "Shoot folder name under /mnt/archive" }
    },
    "required": ["shoot"]
  },
  "run": ["du", "-sh", "/mnt/archive/{{shoot}}"],
  "timeout_seconds": 60
}
Second, a shell-mode skill for when you need a pipeline — the render queue on the export box:
{
  "name": "render_queue_depth",
  "description": "How many export jobs are waiting in the render queue, and which one is oldest",
  "input_schema": { "type": "object", "properties": {} },
  "shell": "ls -1t /mnt/render/queue | wc -l && ls -1t /mnt/render/queue | tail -n 1"
}
Drop the files in, and the agent advertises them automatically (on startup, and it refreshes every ten minutes — no redeploy, no backend config). There's nothing extra to set up in the web UI either: the character already has the Query Server Agent skill, and every new capability you declare simply appears in what it knows about your machines. Then, in the same chat window where you ask your character about photo albums:
You: how big is the Hernandez wedding on the NAS, and is anything still waiting to render?
Character: The 2026-07-12-hernandez-wedding folder is 412 GB on studio-nas. Over on render-1, the queue has three jobs waiting — the oldest is hernandez_highlights_4k.mov. CPU there is at 96%, so it's working through them.
This is an illustrative multi-machine conversation. Inspect actual tool results before treating a reported queue depth or folder size as fact.
The important boundary: the character sees each skill's name, description, and argument schema — never the command line, which stays private on your machine (it embeds your paths and folder layout). It invokes declared commands with model-supplied arguments. An argument-list invocation avoids shell expansion, but does not constrain paths such as ../; validate allowed paths in a wrapper and use a restricted operating-system account. A backup-verification skill wrapping rclone check fits the same shape — "is Tuesday's shoot safely offsite?" becomes answerable, honestly, from the tool's actual output.
The offload station in the corner
Most studios have one: the Mac mini or Raspberry Pi whose whole job is pulling cards at the end of a shoot day — copy, verify, sort into dated folders, kick off the offsite sync. It's the machine you most want to interrogate ("did last night's offload actually finish?") and the one you least want to SSH into at midnight. If your offload script logs a JSON line per file — most are one printf away — that log is a dataset, and the agent makes it conversational: "how many files came off the cards last night?", "did the offsite sync finish?", "what time did the last card complete?" — asked from the couch, answered by the closet.
(For the field-to-library leg itself, Camera to Cloud already handles that as a managed service — your camera uploads straight into your 5AM library with nothing to host. Server Agents are the complement: they cover the machines you do run yourself.)
How the character knows what to ask
A model can only construct a good query if it knows what data exists. Every agent advertises its capabilities — dataset names, field types, time coverage — and when your character starts a turn, that live registry is injected into its tool definition: which machines you have, which are online, and the exact schema of every dataset. That gives the model the information needed to construct a query. It can still choose the wrong operation or interpret a result incorrectly; inspect the returned query and data, especially after a schema change.
The queries themselves are a deliberately structured language — count, count_distinct, group_by, stats, latest, with typed filters and time ranges — not raw SQL. Field names are validated against your schema, operators come from a fixed list, and every value is a bound parameter. A language model authoring SQL that executes on the machine holding your life's work is a sentence that should make you nervous; it made us nervous too, so the dataset-query interface does not accept model-authored SQL. Custom skills remain a separate command-execution boundary.
What a character can — and cannot — run on your machines
This is the part we sweated hardest, because "an AI can query my archive server" is exactly the kind of sentence that deserves suspicion.
The agent's executable surface is exactly two things:
- Dataset queries — the structured, read-only operations above.
- Custom skills you declared — the manifests from the previous section, and nothing beyond them. You write the manifest, you fix the exact command.
There is no third thing. The chat-mode run_command tool is structurally unreachable in the agent — not disabled, absent from the dispatch table. And because a daemon has no human to show a confirmation prompt to, any custom-skill invocation whose expanded command trips our destructive-command screen (rm, dd, kill, …) is refused outright unless you explicitly started the agent with --allow-destructive. This screen is not a proof that a custom command is harmless. A permitted script can still modify files, and --allow-destructive explicitly changes the boundary. Run the agent with limited operating-system permissions and review each manifest before enabling it.
The credentials story follows the same philosophy. Agents authenticate with a normal 5am token — and every agent endpoint deliberately requires only read scope. So the token you leave on the NAS can be minted read-only: if it's ever stolen, it cannot upload, modify, or delete a single byte of your media library.
One character, your whole studio
Agents are named — studio-nas, render-1, portfolio, ingest — and you can register as many as you like. Your character sees all of them, knows which are online, and routes each question to the right machine; one question can fan out across several, like the shoot-size-plus-render-queue answer above. 5am agent list shows the fleet at a glance.
For production it's a handful of systemd units — the agent, a follower per log file, and a timer for whatever you sample. Writing them by hand once is fine (Step 5 above shows the agent one in full), but it gets repetitive across a fleet, so we publish a small installer you can copy and adapt: install-agent.sh. Point it at your log and it writes and starts the lot:
# just the agent
sudo AGENT_NAME=web-1 LOG_FILE= ./install-agent.sh

# agent + follow the nginx log into a `requests` dataset
sudo AGENT_NAME=web-1 ./install-agent.sh

# ...and sample a script every minute into its own dataset
sudo AGENT_NAME=web-1 SAMPLER=/usr/local/bin/sysmetrics.sh ./install-agent.sh
(That last one refers to sysmetrics.sh, the CPU/memory/disk sampler from the same repo — it and its schema are published alongside the installer.)
It's about eighty lines and worth reading before you run it — the useful part isn't the automation, it's the three details that are easy to get wrong by hand: ExecStart needs absolute paths because systemd doesn't search PATH, HOME has to be set explicitly or the CLI can't find the token you logged in with, and a redirect like >> only works inside an explicit sh -c because there's no shell involved otherwise.
Then check it actually worked, which is the step everyone skips:
systemctl status 5am-agent      # active (running)
5am agent list --pretty         # your agent, online: true
That second line is the one that matters. A monitoring setup that is quietly not monitoring is worse than none at all, and online: false is how you find out. The daemon attempts a checkpoint on SIGTERM. After a restart, check that ingestion resumed and compare recent rows with retained source logs; an abrupt power loss is a different failure case.
Where this is going
Server Agents are the first step in a bigger idea: your AI characters shouldn't just know about the media you've uploaded — they should be able to reach the machines your practice runs on, on your terms, with your data staying yours. Picture the morning brief from a scheduled character: "Overnight: three renders finished on render-1, the offload station pulled 212 frames off yesterday's cards, the portfolio log contained 890 distinct IP addresses — and the NAS crossed 80% full, you'll want to prune scratch." Every piece of that is a query this release can already answer; the scheduling is a checkbox your characters already have.
The foundation is live today, in the current CLI:
5am update        # get the latest CLI
5am serve agent --name studio-nas
The installer, metrics sampler, and supporting examples are on GitHub at digvan/5am-cli, Apache-2.0 and yours to copy. Full documentation — schema reference, query operations, the systemd runbook, and the complete security model — lives in the CLI docs and in docs/server-agent.md. Deploy an agent on the machine that holds your work, enable the skill, and ask it something you've always wanted to know. It's been keeping notes for years. Now it can finally answer.